Sample Size for Unpaired t Test
Menu location: Analysis_Sample Size_Unpaired t.
This function gives you the minimum number of experimental subjects needed to detect a true difference DELTA in population means with power POWER and two sided type I error probability ALPHA (Dupont, 1990; Pearson and Hartley, 1970).
Information required
- POWER: probability of detecting a true effect.
- ALPHA: probability of detecting a false effect (two sided: double this if you need one sided).
- DELTA: difference in population means.
- SD: estimated standard deviation for within group differences.
- M: number of control subjects per experimental subject.
Practical issues
- Usual values for POWER are 80%, 85% and 90%; try several in order to explore/scope.
- 5% is the usual choice for ALPHA.
- SD is usually estimated from previous studies.
- If possible, choose a range of differences between means that you want to have the statistical power to detect.
Technical validation
The estimated sample size n is calculated as the solution of:
$\displaystyle n=\frac{(1+1/m)(t_{n(m+1)-2, \space \alpha/2} + t_{n(m+1)-2, \space \beta} )^2}{d^2}$
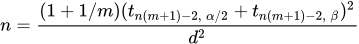
- where d = delta/sd, α = alpha, β = 1 - power, m is the number of control subjects per experimental subject, and tv,p is a Student t quantile with v degrees of freedom and probability p. n is rounded up to the closest integer, then adjusted if necessary to the smallest n for which the power calculated from the non-central t distribution reaches POWER.
Example
Suppose you plan a trial in which a new treatment is compared with placebo and the outcome is systolic blood pressure at the end of treatment. A reduction of 5 mmHg would be worth detecting, and from earlier studies the standard deviation of systolic blood pressure among such patients is about 12 mmHg. You want 90% power at a two sided significance level of 5%, with one control for each treated patient. The figures are invented for this illustration.
To run this in StatsDirect select Unpaired t from the Sample Size section of the Analysis menu. Enter 5 as the difference in population means, 12 as the estimate of population SD, 1 as the number of controls per experimental subject, 90% as the power and 5% as alpha.
For this example:
Sample size for an unpaired two sample Student t test
Alpha = 0.05
Power = 0.9
Difference between means = 5
Standard deviation = 12
Controls per experimental subject 1
Estimated minimum sample size = 123 experimental subjects and 123 controls.
Degrees of freedom = 244
So 123 patients would be needed in each group, 246 in all; the power with these numbers is just over 90%. If two controls were recruited for each treated patient, entering 2 as the number of controls per experimental subject would give:
Controls per experimental subject 2
Estimated minimum sample size = 92 experimental subjects and 184 controls.
Degrees of freedom = 274
Fewer treated patients would then be needed (92 rather than 123) but more patients in all (276 rather than 246): for a given total, groups of unequal size have less power, so an unequal ratio is usually chosen only when experimental subjects are scarce or costly.
 R code
This R code reproduces the example above. It needs no packages and was checked with R 4.6.1. Paste it into R, or save it as a script and run it.
# Sample size for an unpaired t test: the StatsDirect help example (a planned trial
# of a treatment expected to lower systolic blood pressure by 5 mmHg, SD 12 mmHg,
# made up for the help) in R
delta <- 5          # difference in population means worth detecting
sd <- 12            # estimated standard deviation within each group
power <- 0.9
alpha <- 0.05       # two sided
m <- 1              # controls per experimental subject

# power.t.test solves the same two sided non-central t power equation as the report,
# but only for two groups of the same size (m = 1). Its n is per group and is not a
# whole number: the report gives the next whole number, the smallest n whose power
# reaches the target. strict = TRUE counts a rejection in either tail as power, as
# the report does; here the lower tail adds almost nothing.
print(power.t.test(delta = delta, sd = sd, sig.level = alpha, power = power,
                   type = "two.sample", alternative = "two.sided", strict = TRUE))

# For m controls per experimental subject the power of the unpaired t test with n
# experimental subjects (n(m + 1) - 2 degrees of freedom) comes from the non-central
# t distribution, and the report gives the smallest whole n whose power reaches the
# target. The search starts from n = 2, or from the smallest n giving at least one
# degree of freedom when m is below 0.5.
six <- function(x) formatC(x, digits = 6, format = "f", drop0trailing = TRUE)
size_unpaired <- function(delta, sd, m, power, alpha) {
  stopifnot(delta != 0, m > 0)  # a zero difference or ratio has no finite answer
  power_of <- function(n) {
    df <- n * (m + 1) - 2
    ncp <- abs(delta) / (sd * sqrt((1 + 1 / m) / n))
    tcrit <- qt(1 - alpha / 2, df)
    pt(tcrit, df, ncp, lower.tail = FALSE) + pt(-tcrit, df, ncp)
  }
  n <- max(2, ceiling(3 / (m + 1)))
  while (power_of(n) < power) n <- n + 1
  cat("Alpha =", six(alpha), "\n")
  cat("Power =", six(power), "\n")
  cat("Difference between means =", six(delta), "\n")
  cat("Standard deviation =", six(sd), "\n")
  cat("Controls per experimental subject", six(m), "\n")
  # the report rounds the control count down; the power uses m n controls exactly
  cat("Estimated minimum sample size =", n, "experimental subjects and",
      floor(m * n), "controls.\n")
  cat("Degrees of freedom =", six(n * (m + 1) - 2), "\n")
  cat("Power at this sample size =", six(power_of(n)), "\n\n")
}
size_unpaired(delta, sd, m, power, alpha)

# The same trial with two controls for each experimental subject: fewer experimental
# subjects are needed, but more subjects in all
size_unpaired(delta, sd, m = 2, power, alpha)